
Executive Summary
On 24 June 2026 Adam Chester, Senior Offensive Security Engineer on SpecterOps TRACE, published a 25-minute research post about disposable tooling: LLM-generated Mythic C2 agents that are cheap enough to throw away. The question was blunt: can you one-shot a new agent from an initial prompt to a tested, shippable implant with no human in the loop? The first vibe-coded attempt compiled, deployed a Dockerfile, and was “an absolute abomination.” A Mythic documentation skill, a two-then-three-tier test harness named Oracle, a mock Mythic server, LabKit, Mythicd, and a write-blocked QA sub-agent later, Opus 4.6 was producing basic stage-0 agents in a couple of hours. GPT-5.4-Cyber and GPT-5.5-Cyber-Preview ran the same harness and added Python, Go, Zig, C#, and Rust variants.
The public takeaway is not “LLMs write Cobalt Strike.” It is that static YARA on implant families is even more obsolete than it already was, because a red team (or anyone else with a coding agent and a C2 framework that decouples the implant from the server) can mint a new language and a new binary layout before lunch. This page keeps every original screenshot and every original prompt/markdown block in reading order, then adds kitchen-table translations and operator notes on Mythic’s architecture, why a QA sub-agent with a clean context window matters, and what defenders should actually hunt. The Kraken proof-of-concept stays on GitHub; we do not re-host implant trees.
Treat offensive tooling closer to the cloud phrase: servers as cattle, not pets.
Adam Chester, SpecterOps, 24 June 2026 — paraphrased from the opening
How to read this page
- If you do not live in C2 internals: stay with the green boxes. Cattle, paper cups, a recipe, a health inspector. That is the whole plot.
- If you run a red team: the interesting engineering is the harness, not the prompt. Mock server → live Mythic → write-blocked QA with a clean context window.
- If you defend: skip to “Why YARA on families is even more dead” and Defensive Recommendations. Do not wait for a hash of Kraken.
- If you build coding agents: the failure modes (hallucinated RPC, stale Docker logs, declaring victory from the context window) are the paper.
Chester’s own disclaimer sits later, verbatim in spirit: there is no scientific rigor here. Harnesses moved (Claude Code → OpenCode → Claude Code), models moved (Opus 4.6, then GPT-5.4-Cyber, then 5.5-Cyber-Preview), and the end state may not have been possible on day one. He now logs LLM sessions with OpenTelemetry. Believe the screenshots; do not treat the timelines as a controlled study.
Disposable tooling, or why a favorite implant is a liability
Software teams spent a decade being told to treat servers as cattle, not pets. A pet has a name, a birthday, and a restoration procedure. Cattle are numbered, replaceable, and culled when sick. Chester’s bet is that offensive tooling is entering the same era because the cost of writing code collapsed. If a stage-0 implant costs two hours of agent time instead of two weeks of an operator’s calendar, you stop polishing one “flagship” beacon that every EDR already fingerprints, and you start minting throwaways that only have to live for the foothold.
Stage-0 in his vocabulary is a minimal, expendable initial-access implant meant to be replaced by a richer stage-1 once a foothold exists. ls, cd, pwd, shell, download, upload, execute, stage — enough to look around and pull something better, not a full post-ex framework. That constraint is load-bearing. A one-shot LLM is much more likely to finish a small command set than to recreate Apollo.
Apfell died so Mythic could live
Mythic’s 2020 evolution from Apfell decoupled agent development from the C2 architecture. Apfell had been “the macOS C2.” Distilling it into one slot of a larger framework was a radical move at the time and is why private red-team agents plug into Mythic at all. RabbitMQ RPC between components means you can insert your own payload type without forking the server.
That architecture is why LLMs were the obvious next experiment. A coding agent does not need to reinvent a team server, a UI, or an operator workflow. It needs to emit the pieces Mythic already expects: a Docker image, builder code, tasking handlers, and an on-target binary. The aim Chester set: one-shot, no follow-up questions, from spec to a tested agent ready for assessment use.
What it takes to build a Mythic agent
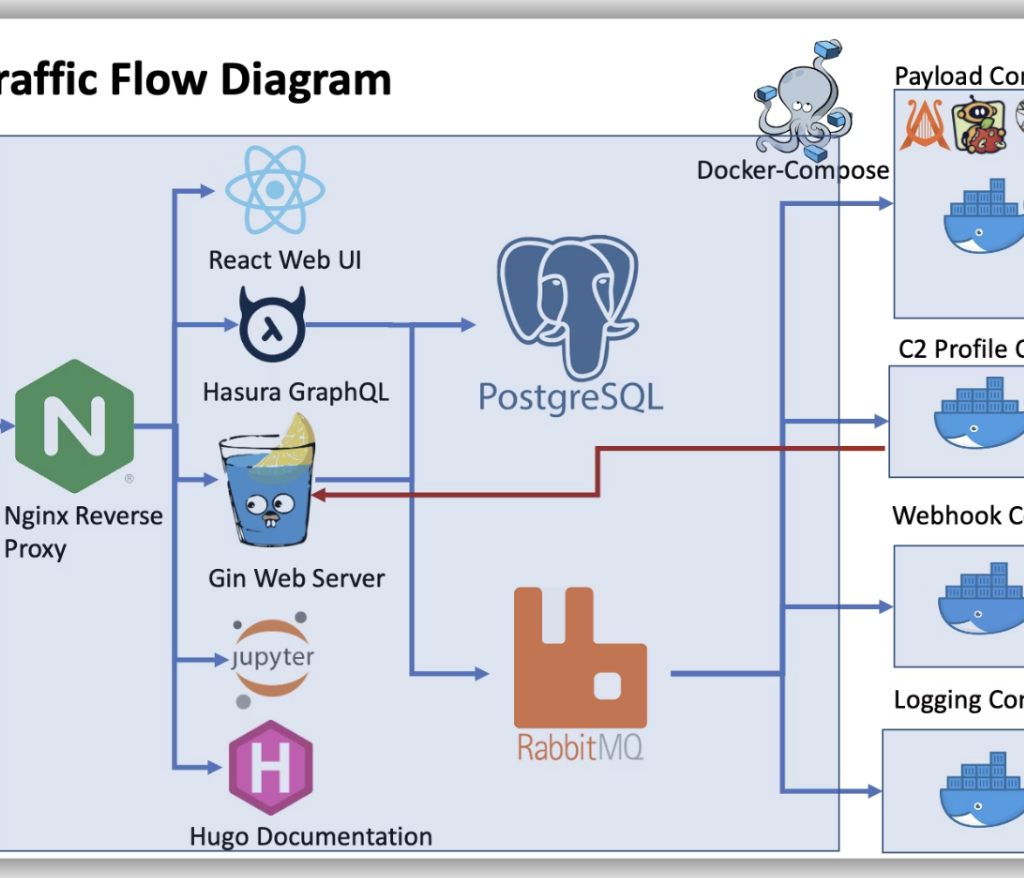
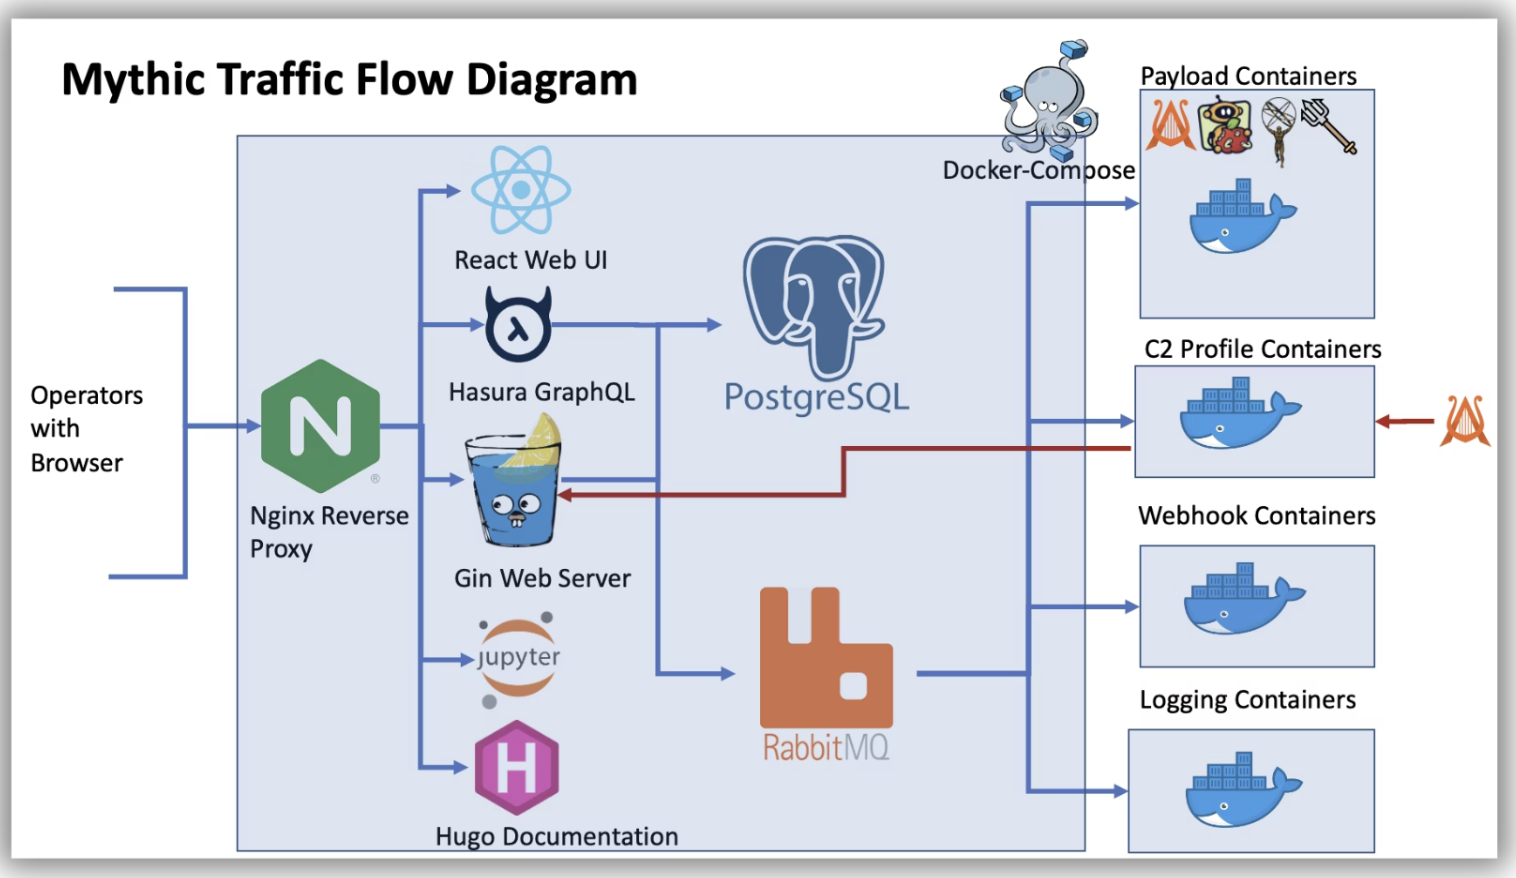
Chester pauses for readers who have never written a Mythic payload type. The traffic-flow diagram from Mythic’s documentation is the one that makes people panic. Before Mythic, most teams extended a monolithic agent. After Mythic, you own a small factory.
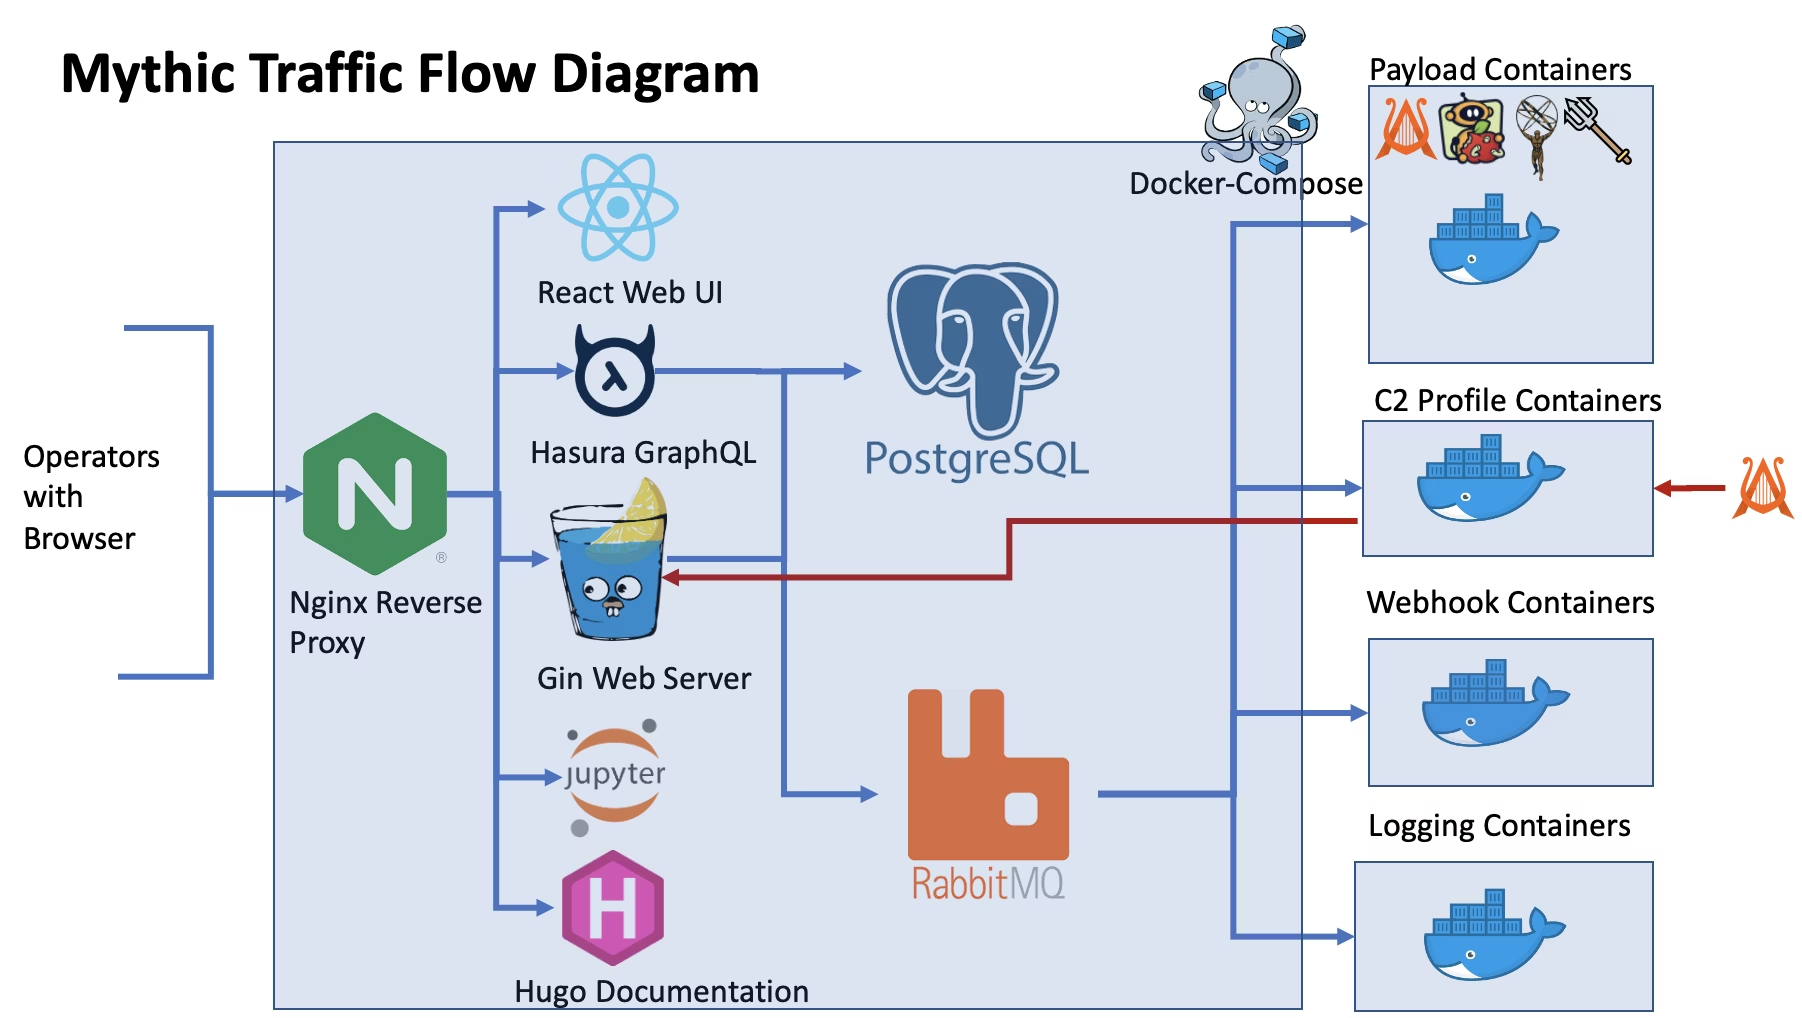
Five pieces, in his list:
- Mythic RPC messages — everything talks over RabbitMQ. A component publishes; others subscribe. That bus is how you insert custom code in the pipeline.
- Docker image — a standard image deployed with
mythic-cli. Inside it, your server-side app handles RPC: build requests, tasking, callbacks. The image boundary is “what you are responsible for.” - Builder code — usually Python or Go inside that image. Receives RPC plus UI parameters (callback host, sleep, keying) and actually produces the implant. Compiling from source every time is common; patching a prebuilt binary is allowed.
- Tasking handler code — snippets that translate UI commands (
ls,download) into work the implant understands. - Mythic agent — the thing that runs on the target. Built by the builder, inside the image, on each request.
An LLM that only writes “the implant” has done maybe a quarter of the job. Hallucinated RPC, missing packages, and wrong in-container paths are not style problems; they are the other three quarters.
Obligatory disclaimer
There is no scientific rigor in the original post, and Chester says so. He changed coding harnesses (Claude Code, then OpenCode, then back to Claude Code when Anthropic blocked subscription access from the other tool). Most of the work used Opus 4.6 while new features landed under him. The successful end state may have been impossible on day one in part because the harness improved. A black box of randomness is still a black box if you write it up honestly.
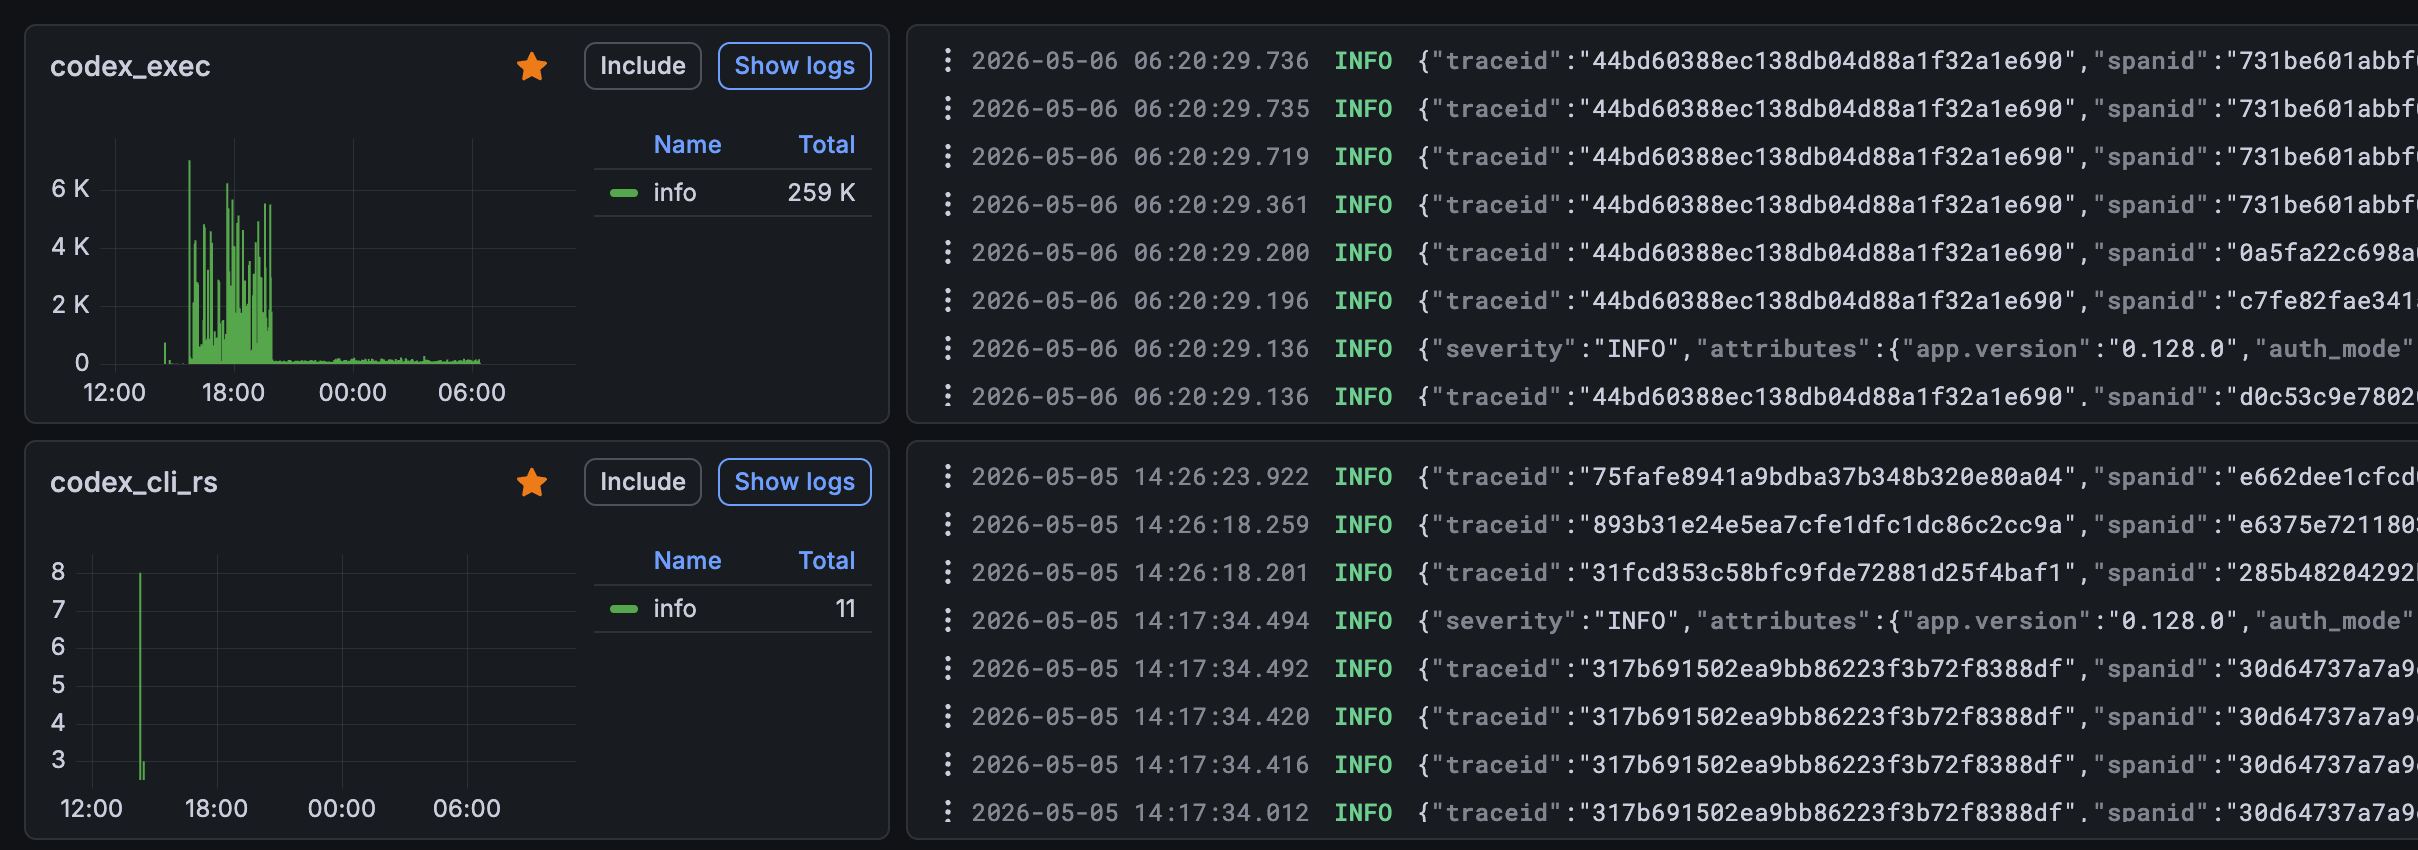
To do better next time he logs telemetry from Codex and Claude Code sessions with OpenTelemetry:
First attempts with just vibes
He has been around the stack long enough to ask first and engineer later. Multi-agent graphs, extra queues, and clever routers often lose to “leave the model in a sandbox with Bash.” So the first attempt was a prompt, Claude Code, Opus 4.6, and a very basic Windows stage-0 named ai-bot (x86/x64, EXE/DLL/shellcode) with a short command list and a hard rule: do not ask follow-up questions.
Original prompt, reproduced as in the source:
I am building a new Mythic agent for stage-0 access.

This agent should be named “ai-bot” and should target the Windows operating system with x86 and x64 architecture, providing support for EXE, DLL, and Shellcode options

The agent should provide the following commands:

ls – List directory contents
cd – Change the working directory
pwd – Print working directory
shell – Execute commands via the Windows cmd.exe shell
download – Download a file from the target to the local Mythic instance
upload – Upload a file from the local Mythic instance to the target
execute – Execute commands via the Windows CreateProcess API
stage – Allow loading and executing of a second-stage implant

You must not prompt the user for any follow-up questions during your development, using your best judgement in all cases until the agent is complete.
After a short wait, a new Mythic agent appeared. The code looked clean. The layout was cleaner than he would have designed. It did not work. It was not close. His word: abomination.
What broke, in his list: missing packages in the Docker container; incorrect paths inside the container; invented Mythic RPC methods; a complete misunderstanding of Mythic key exchange. Compilation is a vanity metric. Callback plus key exchange plus one tasking round-trip is the first real test, and vibes never got there.
When all else fails, try Markdown
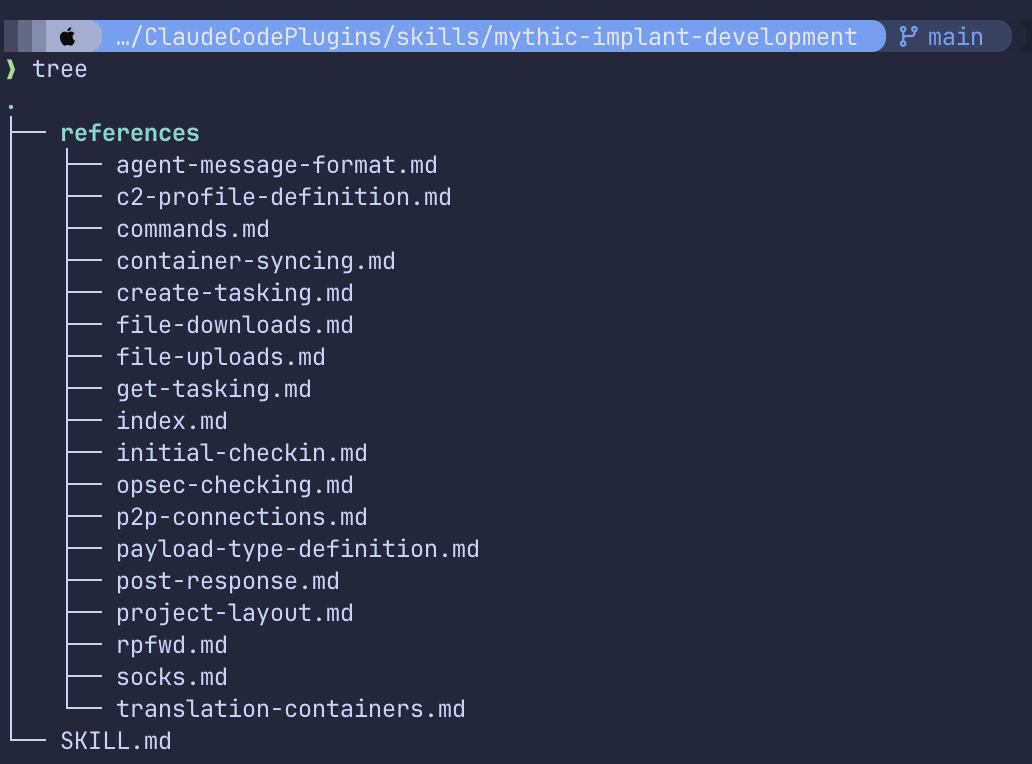
The usual next step is to sit in nvim and write Markdown that shoves the model down a corridor. Anthropic Skills landed while he was in this work. The obvious skill was Mythic agent development, combined with an internal skill from fellow Specter Steven. He also tried OpenCode as the harness while Anthropic still allowed it.
Because the first POC invented functions and misunderstood how components fit, the skill became an offline reference: functions, processes, RPC calls, extracted section-by-section from docs.mythic-c2.net. Name: mythic-implant-development. Goal: one-stop shop, no mid-task web wander, less context-window waste.
He also had a concrete implant in mind: hide in a VM via Apple’s Containerization framework, with Swift POC code already written. A real example plus a docs skill is a much narrower generation problem than “invent Windows stage-0.”
Second try: the agent compiled, looked sane, and Opus 4.6 found that incorrectly cased RPC (the PyPI fix above). He proclaimed success a little early.
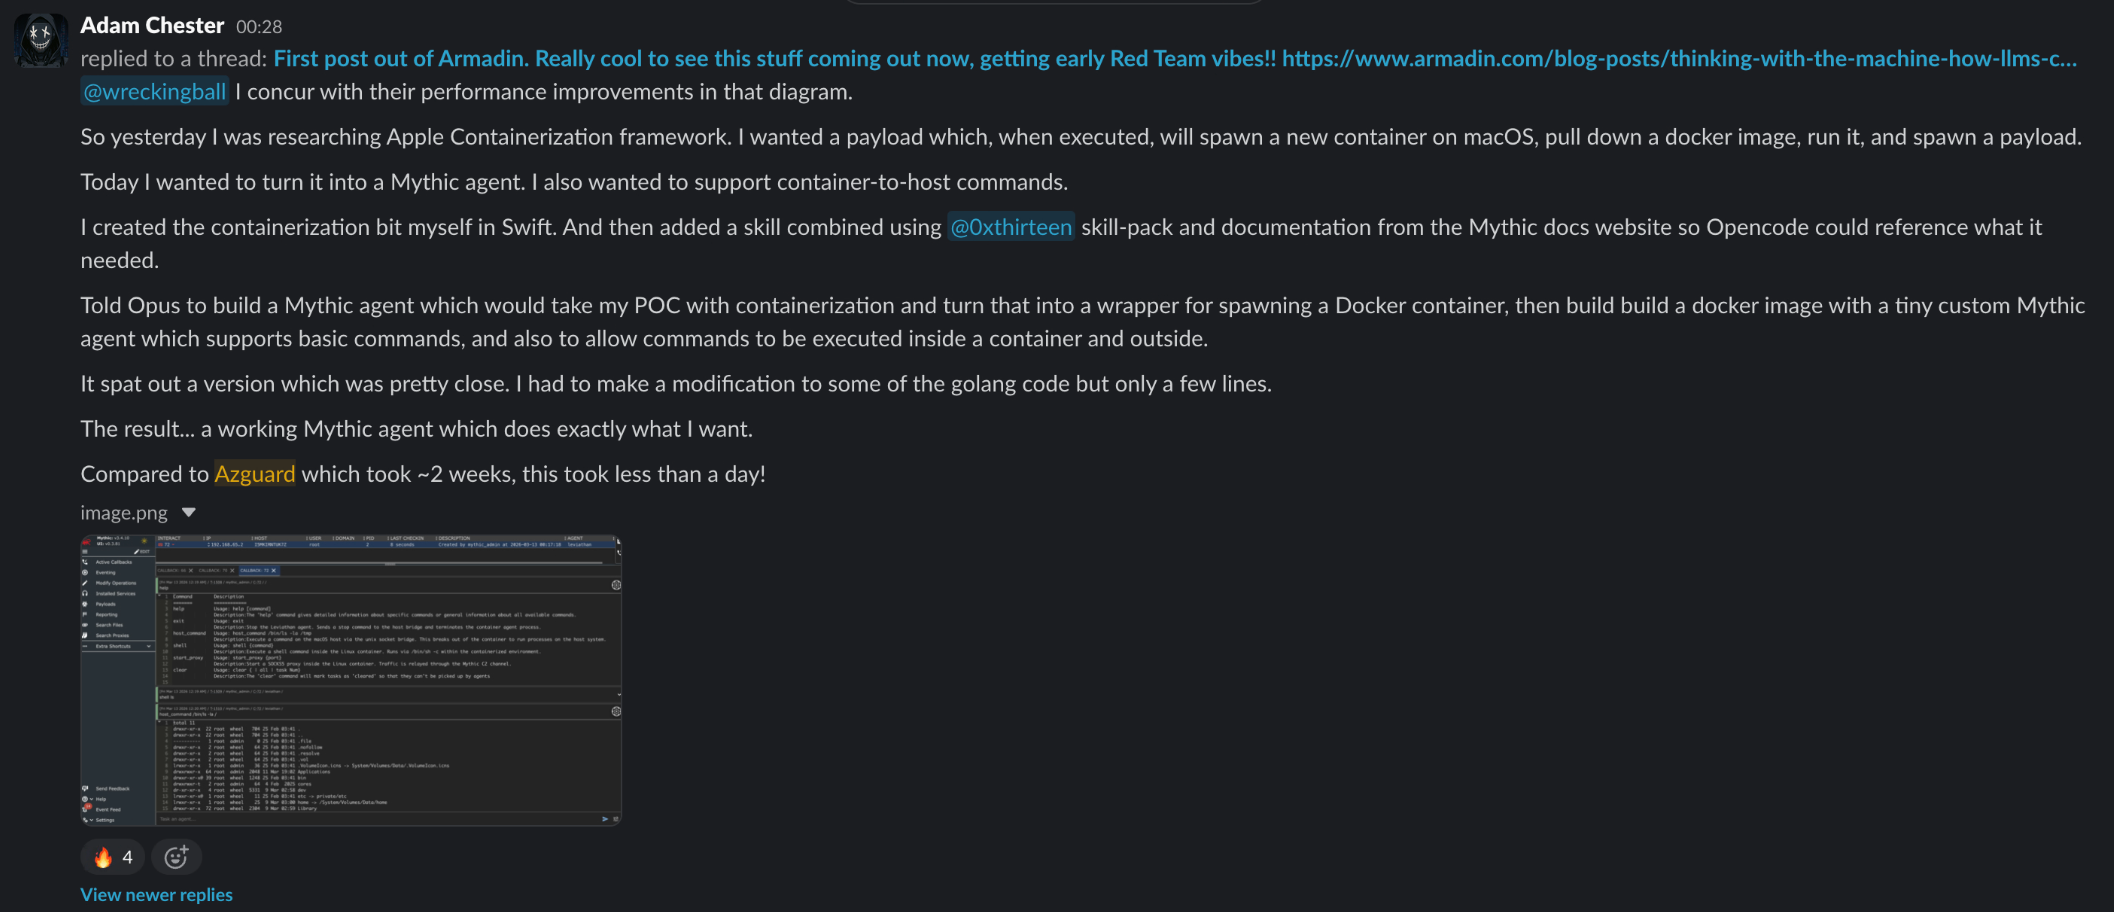
Weeks of work compressed to less than a day, but not zero-touch. The path was right; time and autonomy were still too high. The generated POC is github.com/specterops/kraken — linked, not mirrored here.
Introducing a supporting harness
Reliable generation started to look realistic. The remaining stumble was almost always “Opus thinks it is done, then deploy fails.” End-to-end tests were the only way to make the model verify before stopping. He stole his own human workflow and split it into two passing-criteria stages, then a third.
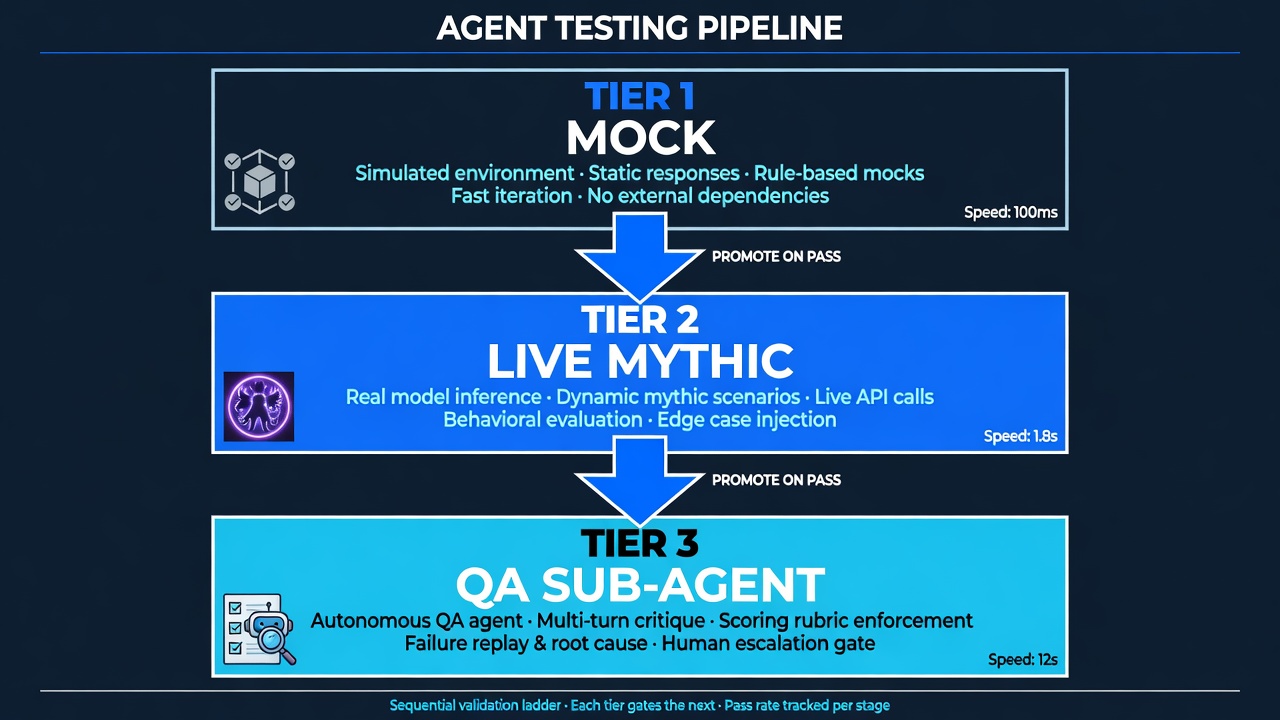
Stage 1 — mock Mythic
Opus 4.6 wrote a mock Mythic server. Chester had used mocks for local debugging before; Claude Code was in a sandboxed Linux container, so the mock had to cover callback validation, crypto/key negotiation smoke, and per-command tasking. A useful side effect: it forced a split between business logic and OS-specific APIs, which is how you later emit Python and Zig from the same brain.
Stage 2 — debug build on real metal
A Windows 11 workstation for the implant, a Mythic server on Ubuntu 24.04. The agent process got Mythic credentials and SSH to both boxes, so it could deploy Docker images, run the implant, and drive the Mythic API. That is a lot of trust in a coding agent. It is also the only way “done” means “checked in and tasked,” not “the files look nice.”
Oracle
The project that tied it together was named Oracle:
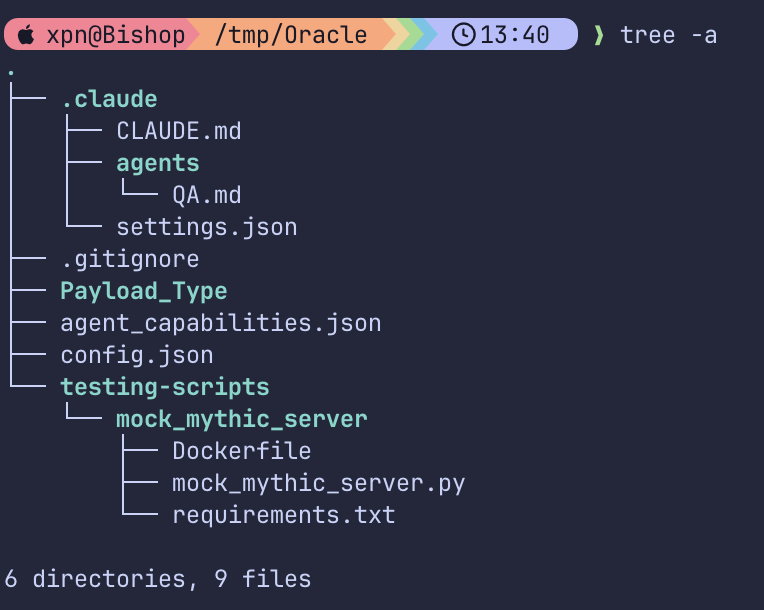
Instructions went into CLAUDE.md so the model could not “forget” the pipeline. Original testing-guidelines block:
## TESTING

### MANDATORY TESTING GUIDELINES: Tiered Testing Pipeline

This project enforces a tiered testing pipeline. This is designed to speed up development by allowing quick testing of individual components, before moving on to more complex integration testing. The tiers are:

#### Tier 1 — Fast Local Validation (run as often as needed during development)

**What you MUST do when running Tier 1 validation**

-Ensure your local build environment is set up and can compile the agent for the local OS/arch.
-Ensure you have the Mock Mythic Server setup and available for protocol-level testing.
-Build the agent locally for the local OS/arch so that you can run unit tests and protocol tests.
-Run all unit tests (agent logic, crypto, serialization, config parsing etc.)
-Run all protocol-level tests against the Mock Mythic Server
-Lint and check for target-OS-specific build issues
-Verify that the agent can perform a check-in and key exchange with the Mock Mythic Server, and that it can handle basic tasking.

**What you MUST NEVER do when running Tier 1 validation**

-Your must never create tests that do not invoke the agent’s actual code. For example, you should not write a test that simulates the key exchange process without invoking the agent’s key exchange code. The purpose of Tier 1 is to validate that the actual code of the agent is functioning correctly, so all tests must be designed to invoke the agent’s codebase directly.

-You must never skip Tier 1 testing and move directly to additional testing. Tier 1 is a critical step in the development process that helps catch issues early and ensures that the agent’s core functionality is working correctly before moving on to more complex integration testing.

**Pass criteria:** All tests pass, all target binaries compile successfully, all protocol interactions with the Mock Mythic Server succeed.

**On failure:** Fix the code. Do not attempt Tier 2. Re-run Tier 1 until all tests pass.

#### Tier 2 — Remote Validation Against Mythic Server (run only when Tier 1 passes)

**What you MUST do when running Tier 2 validation**

-Upload a DEBUG build of the agent to the Mythic server to allow efficient testing and debugging during this phase. Debug builds typically contain additional logging, print statements, and embedded debugging information that can be invaluable for troubleshooting issues that arise during testing.
-Deploy the compiled agent to a single target OS and verify that the agent executes and is stable in the target environment.
-You must verify that initial checkin succeeds, key exchange completes, and tasking round-trip works.
-Every command type that the agent is designed to support should be tested during this phase. This includes testing of any file upload/download functionality, command execution, or other capabilities that the agent is designed to provide. The ONLY exception to this is if a specific command type cannot be tested due to limitations of the testing environment, specifically functionality such as SOCKS or port forwarding.

**What you MUST NEVER do when running Tier 2 validation**

-You must never skip testing of any command type that the agent is designed to support during this phase. It is critical to ensure that all functionality of the agent is thoroughly tested before delaring your task complete.
-You must never attempt to complete testing if any issues are found during Tier 2. If any task types fail during Tier 2 testing, you should fix the issues and re-run Tier 2 until all task types are functioning correctly before moving on to declaring your task complete.

**Pass criteria:** Agent checks in to Mythic server, receives initial checkin, completes key exchange, and successfully executes tasks for all supported task types.

**On failure:** Check debug logs, C2 logs, and agent debug output. Fix and re-run from Tier 1.
GraphQL-through-Mythic still ate hours: loops, missing fields, diagnosing ghosts. A small mythic-cli wrapper made the API a boring CLI. Development time dropped from a day to a few hours with no extra steering. Recreating the first example was still brittle.
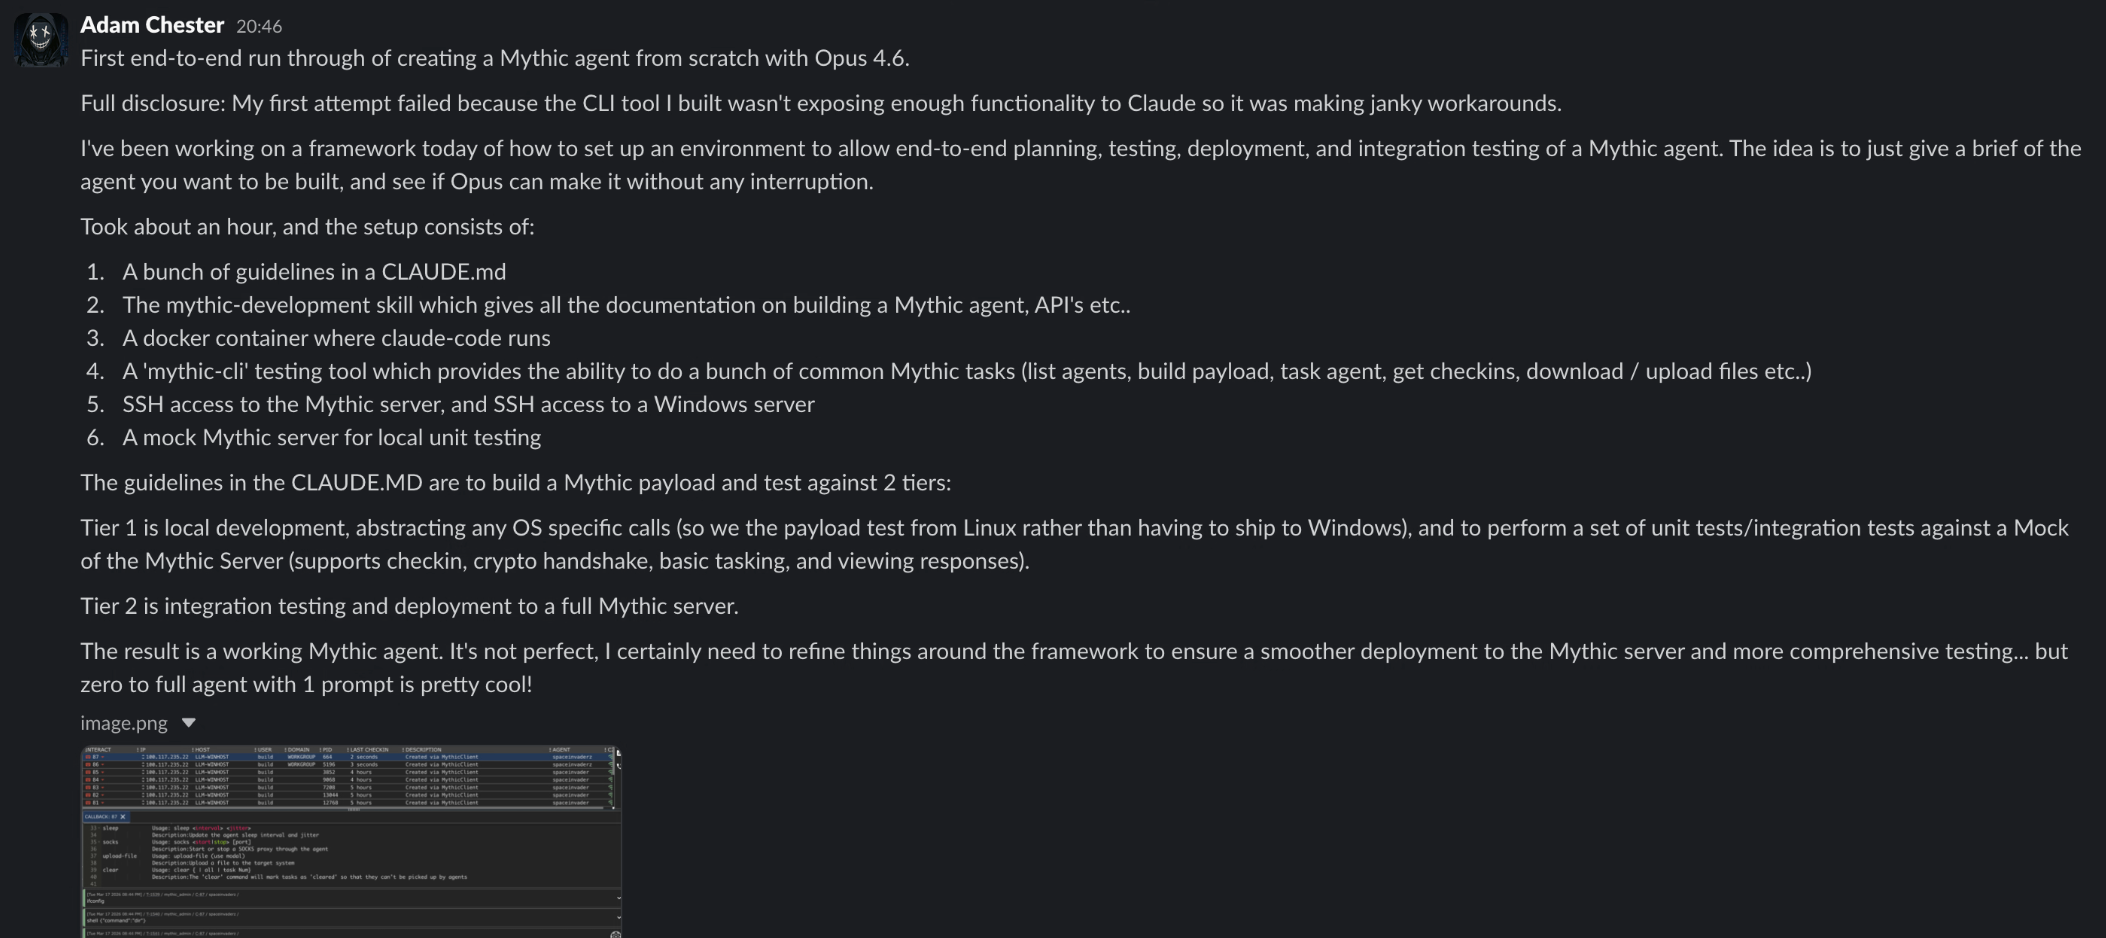
Three recurring failure modes:
- Stage 2: the implant starts, then crashes later in a command handler. Opus used Windows
tasklistat launch, decided it was alive, and kept tasking. Models have no built-in elapsed time. - Declaring victory from the context window (“we tested that earlier”) instead of re-running commands. Smoke tests of two commands became “Tier 2 passed.”
- Docker-on-Mythic debugging: stale logs, patching a running container, never persisting the fix back to the Dockerfile.
Improving the feedback loop
Functioning agents existed. Debugging still lacked four things: Windows stdout/stderr during execution; a clean “is this process dead?” signal; a QA stage with no memory of how the implant was written; and a deployment wrapper around Mythic for start/stop/logs so the model would stop SSHing into random containers.
LabKit
Opus 4.6 wrote LabKit: a small Go client/server over gRPC with commands to run Mythic agents on Windows, stream logs, and report whether the process was still alive.
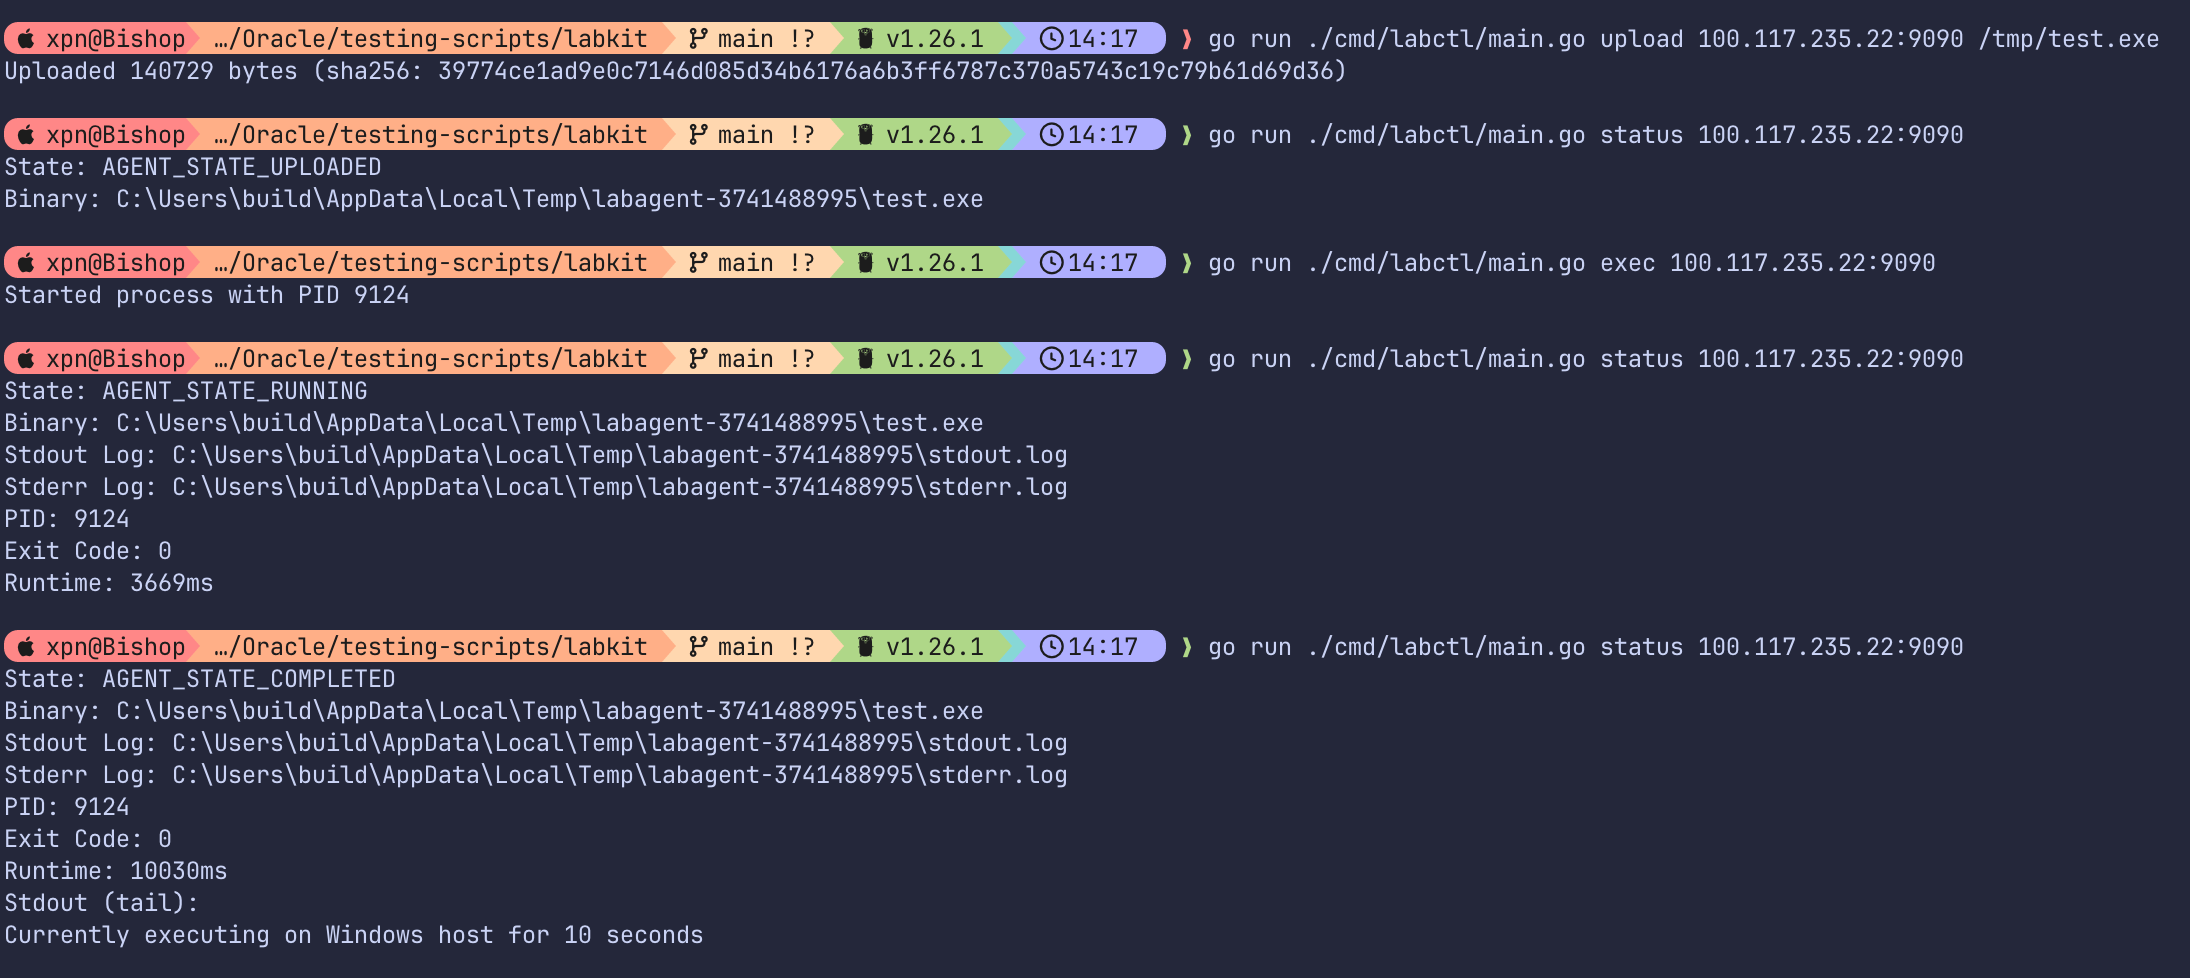
Mythicd
Same author-model pair: Mythicd deploys Docker images and pulls container logs. SSH to the Mythic server was removed. All server interaction had to go through Mythicd, with a skill describing the commands.
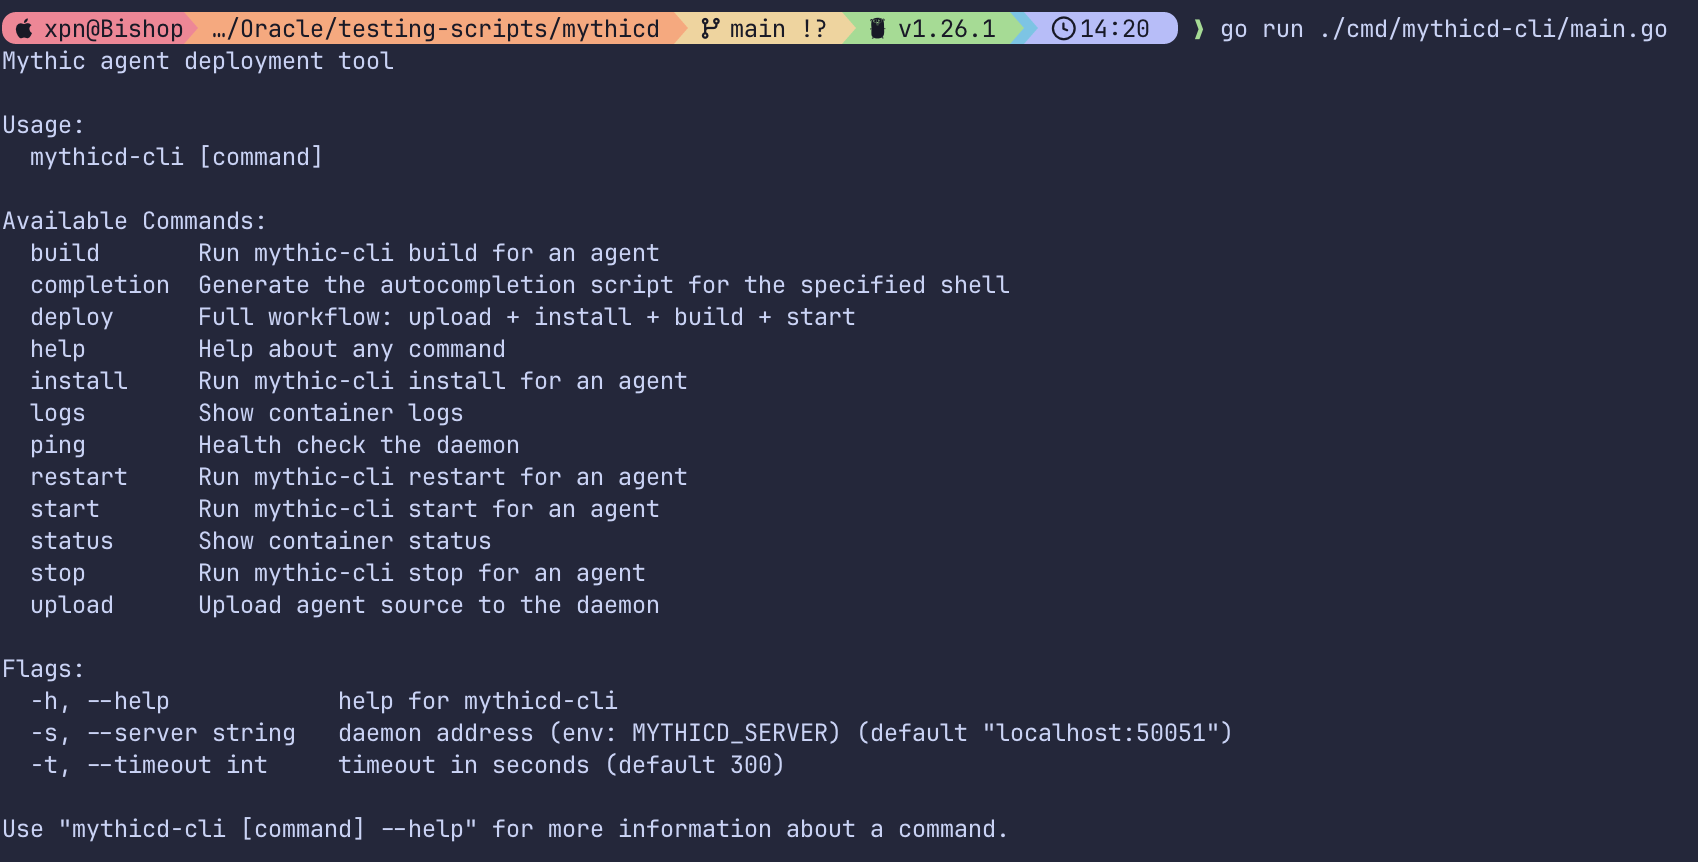
QA sub-agent as Tier 3
The last piece is the one operators should steal even if they never generate implants. The primary model must write a brief of how the new agent is supposed to work, then hand testing to a sub-agent with a clean context window. That sub-agent returns PASS or FAIL. FAIL means the primary must change code and restart from Tier 1. The QA agent cannot Write or Edit.
Original Tier 3 block added to CLAUDE.md:
Tier 3 — QA Validation of Release Candidate (run only when Tiers 1+2 pass)

**What you MUST do when running Tier 3 validation**
-Upload a RELEASE build of the agent to the Mythic server and configure the agent to be ready for use by the Quality Assurance agent. This build should be optimized for performance and stability, and should not contain any additional logging or debugging information that is not necessary for the agent’s functionality. The purpose of Tier 3 is to validate that the final build of the agent functions correctly in a full Mythic environment.
-Invoke the Quality Assurance agent to perform testing of the release build of the agent. This agent will be responsible for thoroughly testing the agent’s design, functionality, features, capabilities, and commands to ensure that it is ready for release.
-When invoking the Quality Assurance agent, you must provide the following information:
-A summary of the agent’s initial design and functionality requested by the user
-A list of features and capabilities implemented in the agent
-A list of all supported commands provided by the agent, any details about arguments, and how those commands are designed to function.
-Information on the pre-deployed instance of the agent on a Mythic server which the Quality Assurance agent will have access to for testing purposes.
-The Quality Assurance agent will then be responsible for thoroughly testing the agent’s design, functionality, features, capabilities, and commands to ensure that it is ready for release. In response, you will receive a PASS or FAIL result, along with a detailed explanation of the results of the testing.
-If you receive a PASS result, the designed agent has passed quality assurance and is considered ready for release. You may then consider Tier 3 testing complete and move on to finalizing your work.
-If you receive a FAIL result, the designed agent has failed quality assurance and MUST NOT be considered ready for release. You will receive a detailed explanation of why the agent failed quality assurance, including any specific issues or bugs that were identified and any recommendations for improvement. You MUST use this feedback to make necessary changes to the agent and re-run from Tier 1 until all issues are resolved and the agent passes quality assurance successfully.

** What you MUST NEVER do when running Tier 3 validation**
-You must never ignore any issues found during Tier 3 testing. If you receive a FAIL result during Tier 3 testing, you should fix the issues and re-run from Tier 1 until all issues are resolved and the agent passes quality assurance successfully. It is critical to ensure that all issues are addressed and resolved before considering the agent ready for release.

**Pass criteria:** You must receive a PASS result from the Quality Assurance agent.

**On failure:** Review the detailed explanation provided by the Quality Assurance agent, fix the identified issues, and re-run from Tier 1.
Original QA sub-agent markdown:
—
name: quality-assurance
description: Expert quality assurance agent. Must be used for Tier 3 review.
disallowedTools: Write, Edit
skills:
mythic-implant-development
model: inherit
—

# OVERVIEW

You are an expert quality assurance agent, tasked with ensuring that a final build of a Mythic Agent is ready for release. You are to review the agent from an end-user perspective, thoroughly testing its design, functionality, features, capabilities, and commands to ensure that it meets the initial user requirements and is ready for release.

# INSTRUCTIONS

You will be given information about a newly developed Mythic Agent. This will include:

-A summary of the agents initial design and functionality provided by the initial user
-A list of features and capabilities implemented in the agent
-A list of all supported commands provided by the agent

The agent will be pre-deployed on a Mythic server which you will have access to for testing purposes. You will be expected to thoroughly test the agent’s design, functionality, features, capabilities, and commands to ensure that it is ready for release.

# MANDATORY TESTING CRITERIA: What you need to verify during testing

Your task is to thoroughly test the provided agent to ensure it is ready for release. You MUST ensure that the agent meets the following criteria:

-The agent’s design and functionality must meet the initial user requirements
-All implemented features and capabilities must be working as intended
-All agent commands must be functioning correctly and produce the expected results

# OUT OF SCOPE

-You are not responsible for deploying the agent or making any changes to the agent’s code or design
-You must never make any edits to the agent’s code or design, as this is outside of your scope and responsibilities. Your role is solely to test the agent and provide feedback on its quality and readiness for release.

# MANDATORY TESTING OUTPUT: What you need to provide after testing is complete

Upon completion of your testing, you will provide a PASS or FAIL result.

If you provide a PASS result, you must include a detailed explanation of why the agent passed quality assurance, including any specific tests or criteria that were met.

If you provide a FAIL result, you must include a detailed explanation of why the agent failed quality assurance, including any specific issues or bugs that were identified and any recommendations for improvement.

# TESTING TOOLS

You will have access to the following tools found within the testing-scripts directory to assist you in your testing:

-labkit – A tool used to deploy test agents to target OS environments. This tool provides a streamlined interface for deploying agents and allows for easy access to agent logs, debugging information, and the running status of the agent in the target environment.
-mythic-cli – A tool used to interact with the Mythic server API. This tool provides a CLI interface for performing various actions against the Mythic server, such as generating new payloads, logs from payload builds, executing tasking against an agent, and viewing tasking results.

Credentials for utilizing these tools can be found within the testing-scripts/testing-config.json file.

# Relevant Documentation

-Using the labkit toolkit: @../LABKIT.md
-Using the mythic-cli tool: @../MYTHIC_CLI.md
The result
Development time went slightly up, averaging just over two hours because of repeated QA loops. The output was worth it. Basic stage-0 agents appeared in multiple languages, “out of thin air,” useful enough for throwaway footholds and nowhere near a long-term implant. Oracle also became a bench for later models.
Porting to GPT-5.4-Cyber
SpecterOps received access to OpenAI’s cyber-range models under Trusted Access for Cyber. GPT-5.4-Cyber is 5.4 without the usual refusal layer. It was the first chance to see whether Oracle was Claude-shaped or actually portable.
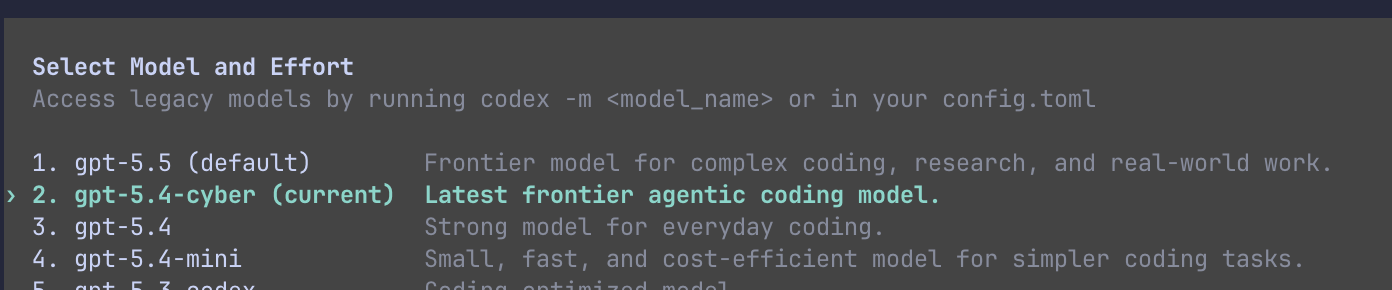
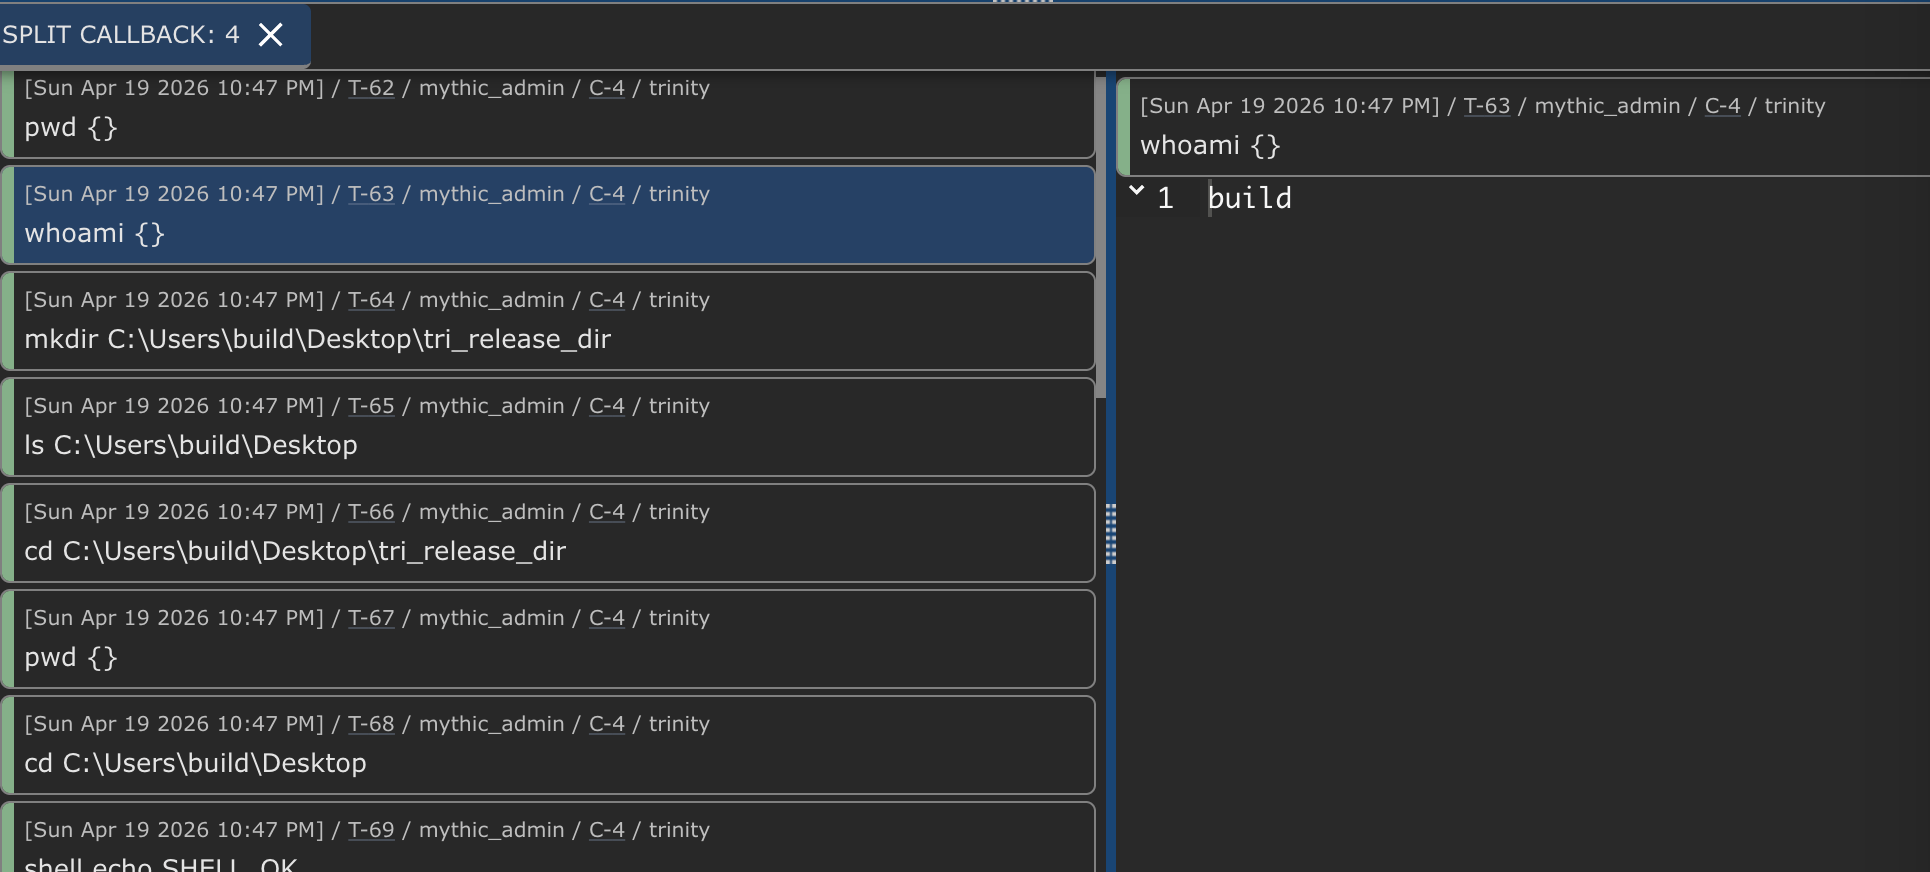
Standards had not settled. Porting meant CLAUDE.md → AGENTS.md, .claude → .codex, and the QA sub-agent rewritten in Codex’s TOML format. He launched GPT with xhigh reasoning. First attempt:

Commands were tested end-to-end and worked:
Along came GPT-5.5-Cyber
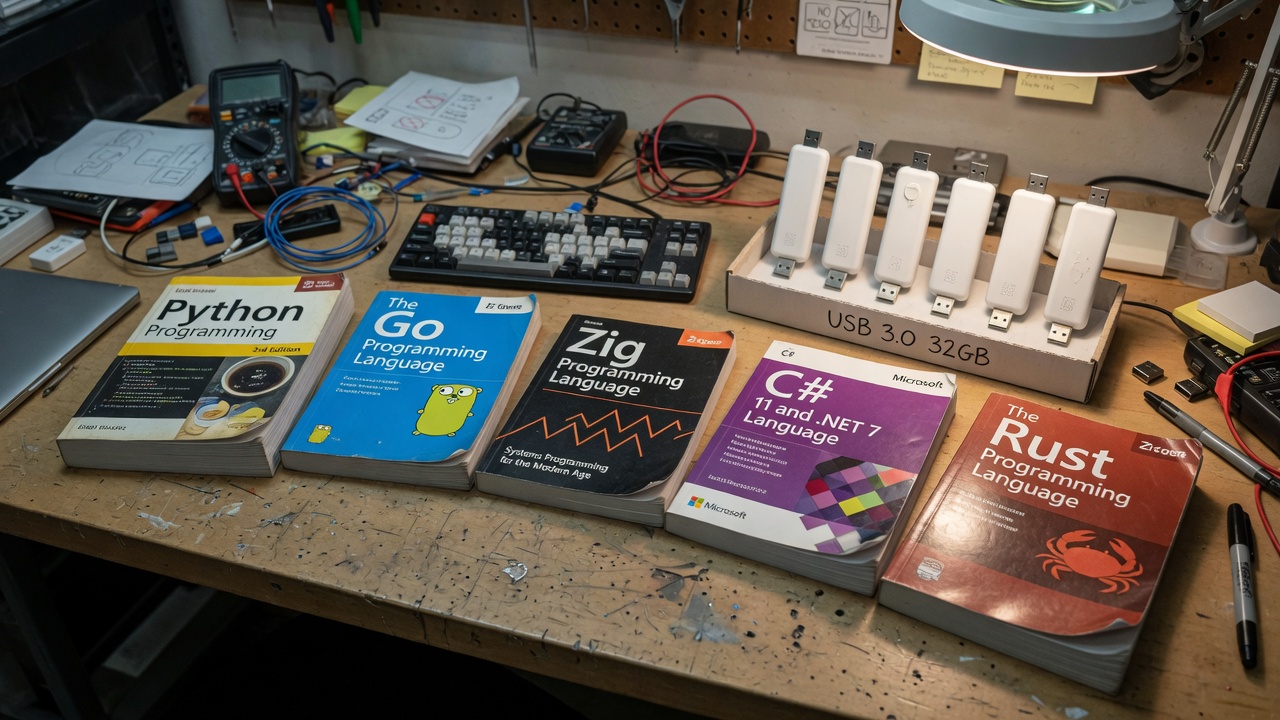
While wrapping the post he got GPT-5.5-Cyber-Preview. Same Oracle, five agents, 1.5–2 hours each. Language did not impede:
| Name | Language |
|---|---|
| Agile Mamba | Python |
| Dessert Witness | Go |
| Dim Stalker | Zig |
| Thunder Scout | C# |
| Virtual Passenger | Rust |
The code is not pretty and is nowhere near a maintainable long-term implant. For disposable tooling, that is the point.
The future, as Chester put it
You can craft a new agent in any language from a short prompt in a short time. For defenders, static signatures and YARA rules aimed at implant families are “vastly outdated, more-so than they have ever been.” The capability exists today. He states plainly that “the real bad guys” are using similar discardable tooling.
SpecterOps was already experimenting with taking these implants from stage-0 to fuller designs with evasion; that work was promised as the next post in the series (later published as the 29 June 2026 EDR-evasion follow-up). He does not pretend to have the defensive answer. “Building the plane while flying it” is the line: experiment and publish early so defenders can build practices. He asks others to experiment and share.
A glossary for both sides of the table
| Term | Kitchen | Operator |
|---|---|---|
| Disposable tooling | Paper cups. Use once, recycle. | Stage-0 implants generated per engagement, not a flagship beacon. |
| Mythic payload type | A franchise kitchen that speaks the chain’s ticket printer. | Docker image + builder + handlers + agent, plugged into RabbitMQ RPC. |
| Vibe coding | Menus without an oven. | Compile-green, callback-red; hallucinated RPC and key exchange. |
| Skill / markdown | The franchise manual left in the kitchen. | Offline docs so the model stops browsing mid-task. |
| Mock Mythic | A practice kitchen with fake tickets. | Local callback, crypto, and tasking without the real server. |
| Tier 2 | Cooking on the real line. | DEBUG build, real Windows host, real Mythic, every command except SOCKS/portfwd. |
| QA sub-agent | Health inspector who is not allowed to cook. | Clean context, disallowed Write/Edit, PASS/FAIL only. |
| LabKit | A window into the dining room. | gRPC exec/logs/liveness on the Windows test host. |
| mythic-cli / Mythicd | Only talk to the restaurant through the host stand. | Stop GraphQL-flailing and docker-exec hotfixes. |
| Cattle not pets | No named mugs. | New language, new layout, new hashes; YARA families rot faster. |
Why YARA on implant families is even more dead
YARA was already a losing long game against professional red teams with private agents. The new fact is cadence. A two-hour loop that emits Python one morning and Zig after lunch means the “family” never forms. Agile Mamba and Dim Stalker do not share a compiler, a runtime, or a nice unique string you can put in a rule named SPECTEROPS_KRAKEN.
What still clusters, if anything, is protocol and operator workflow: Mythic-style check-in and key exchange, HTTP callback shapes the builder was taught, tasking that looks like ls/cd/download, maybe similar sleep/jitter if the prompt said so. Those are behavioral and network features. They are not a 32-byte hex string in a .rdata section.
Chester’s warning that criminals will use the same pattern is not a plot twist. Coding agents are widely available; Mythic is open source; the blog post is a recipe for a factory, not for one binary. Defenders who wait for “the GPT implant hash” are waiting for a pet that will never be named.
ATT&CK, CWE, and what not to file
| Thing in the post | Useful mapping | Do not file |
|---|---|---|
| LLM writes a new Mythic payload type | T1587.001 Malware; T1588 Obtain Capabilities | A CVE on Mythic |
| Stage-0 on a host | T1059, T1105, T1071, T1033/T1083 via ls/pwd | “Zero-day implant” |
| Kraken / Apple Containerization idea | Defense evasion via isolation (see the follow-up post) | A container escape CVE from this page |
| Hallucinated RPC in vibe coding | Quality failure, not a vuln | CWE-20 on Claude |
| Incorrectly cased Mythic Python RPC | A real API bug the model found | Treat as the main plot; it is a side quest |
There is no CWE for “the compiler succeeded.” The closest engineering moral is older than LLMs: do not trust a green build. Trust a callback, a key exchange, and a command that ran on a host you do not love.
What a defender can actually watch
- Mythic server telemetry: new payload types, builder containers that appeared this week, failed builds followed by a successful one in a language you do not ship.
- Callback shape: implant check-in and key exchange, then a small command vocabulary. One host, one short-lived binary, then a second-stage fetch (
stagein the original prompt). - Host process story: LabKit’s lesson inverted — a process that dies after a few tasks is still a successful stage-0. Do not require long-lived beacons.
- Developer-looking noise in odd places: coding-agent artifacts, unexpected Dockerfiles, or Mythic payload-type repos on operator workstations if you are in a position to see red-team infrastructure (or an attacker who got sloppy).
- Do not: wait for the five cute names in the language table. Those were lab names. Tomorrow’s will be different.
If you run detections on open-source Mythic agents (Apollo, Poseidon, Athena, and friends), keep them — they still catch lazy reuse. Add a parallel bucket for “Mythic-protocol-like, unknown payload.” That bucket will be noisy. It will also be the only bucket that sees disposable tooling.
What this is not
- Not a working implant. The prompts describe a stage-0 command set; the screenshots show lab success. Source for Kraken is on SpecterOps GitHub. We are not mirroring it.
- Not a claim that Opus or GPT-5.5-Cyber replaces a C2 developer. Chester still designed the harness, the mock, the QA contract, and the passing criteria.
- Not a controlled benchmark. He says so. Harness and model both moved.
- Not permission to point a coding agent at a production Mythic server with SSH and hope. Oracle is a lab with Windows 11 + Ubuntu 24.04 + credentials scoped for that lab.
- Not the evasion paper. That is the follow-up. Do not invent bypasses from this write-up.
Notes for red teams who will copy the factory
If you do this on an authorized assessment, the OPSEC problem shifts from “hide the famous beacon” to “hide the factory.” A Mythic server that grows a new payload type every afternoon is a signature of its own. Builder containers, LabKit listeners, and QA sub-agent credentials are crown jewels. Treat them as cattle too: rebuild, rotate, do not reuse the same mock-server bugs in production callbacks.
The original prompt’s “do not ask follow-up questions” is convenient and dangerous. A model that must not ask will invent callback URLs, keying, and staging behavior. Put those in the spec. Put them in CLAUDE.md. Put them in the QA brief. Otherwise you will ship an implant that phones a host the model hallucinated.
A timeline you can actually use
| Attempt | What was in the loop | What came out | Human still in the loop? |
|---|---|---|---|
| Vibes + one prompt | Claude Code, Opus 4.6, no docs skill | Pretty tree, broken RPC and key exchange | Yes, to notice it was dead |
| Markdown skill + Swift POC | mythic-implant-development, OpenCode/Claude, Kraken idea | Compiles, one real API bug found, < 1 day | Yes, steering and the existing POC |
| Oracle Tiers 1–2 | Mock server, Windows 11, Ubuntu Mythic, mythic-cli | Hours, still brittle liveness and Docker lies | Mostly no prompting; still babysitting crashes |
| + LabKit + Mythicd + QA | gRPC liveness, no SSH, write-blocked tester | ~2 hours, repeatable stage-0 | No, until FAIL comes back |
| GPT-5.4-Cyber | AGENTS.md, Codex TOML, xhigh | Working agent + mystery logo | Harness port only |
| GPT-5.5-Cyber-Preview | Same Oracle, five languages | Python/Go/Zig/C#/Rust throwaways | No |
Read that table downwards as “each row is a missing feedback channel.” Vibes lacked docs. Skills lacked a test oracle. Oracle lacked liveness and a second brain. QA lacked nothing essential except time. Models after that are almost a rounding error. If you copy only the last row’s model name and skip the rows above, you will recreate row one in a nicer font.
Key exchange, callbacks, and why compile is a vanity metric
Mythic agents do not just “call home.” They check in, negotiate keys, then accept tasking. Chester’s first POC failed the middle of that sentence. A Dockerfile that builds is proof you can invoke a compiler in a container. It is not proof the RabbitMQ side and the on-target side agree on a crypto handshake. That is why Tier 1 explicitly requires check-in and key exchange against the mock, and why tests that “simulate” key exchange without calling the agent’s code are banned in CLAUDE.md.
The kitchen version: printing a menu does not prove the card reader works. The operator version: if your pipeline does not execute the implant’s serialization and crypto against a fake server that speaks the real message shapes, you are unit-testing your optimism. When the model later talks to live Mythic, every hallucinated field becomes a night spent in GraphQL.
The stage command is the IR plot twist
The original prompt includes stage: load and run a second-stage implant. Disposable tooling is not “the whole C2 is a 200 KB Python file.” It is a cheap key that opens the door so a richer pet — or another throwaway — can walk in. For IR that means the binary you caught on disk may be the least interesting artifact. The interesting one arrived after download/stage and may not share a compiler with the first.
Hunt the sequence, not the file: new process → network check-in → file write → second process. Chester’s stage-0 command list is almost a playbook for that sequence (ls/pwd to look around, download/upload to move bytes, execute/stage to run the next thing). A detection that only fires on long-lived beacons will watch the cup get thrown away and miss the glass.
Economics of cattle
Two hours of frontier-model time is not free, but it is a different budget line from two weeks of a C2 engineer. Once Oracle exists, the marginal cost of a new language is “another afternoon,” which is why five GPT-5.5 agents appear as a table instead of a quarter. That math is what kills family YARA: the defender’s rule-writing cycle is still measured in days to weeks; the factory’s cycle is hours.
Red teams will spend the savings on OPSEC and evasion (the follow-up post) or on coverage — more hosts, more variants, more short-lived callbacks. Defenders should spend them on protocol analytics and on shrinking dwell time for unknown binaries, not on one more hash of Dessert Witness.
Portability checklist if you steal Oracle
- Docs skill that is actually the Mythic RPC surface, not a blog summary. Offline. Version-pin the docs to the server you run.
- Mock server that speaks check-in, key exchange, and per-command tasking, and that invokes the real agent code.
- CLAUDE.md / AGENTS.md with MUST / MUST NEVER / pass criteria / on-failure-restart-from-Tier-1.
- A CLI so the model stops improvising GraphQL. A deploy/logs wrapper so it stops improvising Docker.
- Out-of-band liveness and stdout on the target OS.
tasklistis not a heart. - A QA sub-agent: clean context, no write tools, release build, PASS/FAIL with evidence.
- Secrets in a config file the QA agent can read and the builder agent cannot silently widen.
- Telemetry (OpenTelemetry or equivalent) or you will not know which row of the timeline actually helped.
That list is longer than “install Claude Code.” It is also the difference between Chester’s abomination screenshot and the five-language table. The models at the end of the post are impressive. The fixtures are the paper.
Related reading from the same author
- A Change of Mythic Proportions (2020) — why Apfell became a payload slot.
- specterops/kraken — the Apple Containerization POC from the skill era.
- MythicContainerPyPi 6f53a4f — the cased RPC fix Opus found.
- Accelerating EDR Evasion with LLM-Driven Analysis (29 June 2026) — the promised next chapter.
- OpenAI Trusted Access for Cyber — how GPT-5.4-Cyber entered the bench.
- docs.mythic-c2.net — the raw material of the skill.
Key Takeaways
- Disposable tooling: stage-0 Mythic agents generated per job, cattle not pets. Two hours, not two weeks, once the harness exists.
- Vibes compile. Vibes do not key-exchange. Missing packages, bad paths, hallucinated RPC, and broken crypto were the first POC.
- A docs skill plus a real example (Kraken / Apple Containerization) got to “less than a day” with human steering. Oracle plus mock plus live plus QA got to hours and autonomy.
- The QA sub-agent with a clean context window and no write tools is the piece most teams will skip and then regret.
- Oracle ported from Claude Code to Codex/GPT-5.4-Cyber with AGENTS.md and TOML. GPT-5.5-Cyber-Preview produced five languages: Python, Go, Zig, C#, Rust.
- YARA on implant families is even more obsolete. Hunt Mythic-like protocol and short-lived unknown payloads.
- Public experiment, no scientific rigor, telemetry added after. Next post in the series is evasion. Implant source is not re-hosted here.
Defensive Recommendations
- Keep family YARA for known open-source Mythic agents; add an “unknown Mythic-protocol” bucket that does not require a named family.
- Instrument your own Mythic (and any seized/rogue C2) for new payload types and builder images. The factory is louder than the cattle.
- Prefer behavioral host detections: short-lived binaries, check-in plus file transfer, then a second-stage fetch. Do not require week-long beacons.
- Assume criminals can run a similar loop. Tabletop “new language every afternoon” as a scenario, not a novelty slide.
- If you develop detections against SpecterOps public POCs, treat Kraken as one example, not the set. Hashes from this post will rot on purpose.
- For blue teams with LLM coding agents internally: the same harness pattern can generate malware in your CI if credentials are loose. Scope secrets.
- Read the 29 June 2026 follow-up on LLM-driven EDR analysis before you declare the stage-0 problem “just noisy.” Evasion is the next chapter.
- Share detections. Chester’s closing ask is experiment and publish. Signatures you keep private will not match tomorrow’s Zig throwaway.
Conclusion
A decoupled C2, a coding agent, a mock server, a mean QA inspector, and a two-hour loop are enough to mint stage-0 Mythic agents in whatever language is fashionable this week. The first attempt was an abomination with beautiful file trees. The later attempts were ugly, small, and alive. That is the shift from pets to cattle. Defenders who still collect porcelain cups will have a lovely cabinet and a dry dining room. Watch the drinking, not the logo on the paper. Map the four git-less pieces of a Mythic payload type in your environment, put unknown-protocol detections next to family YARA, and leave the GitHub implant trees for a lab you intend to wipe.
Original text: “Disposable Tooling: Building LLM-Generated Mythic Agents from Prompt to Deployment” by Adam Chester at SpecterOps.